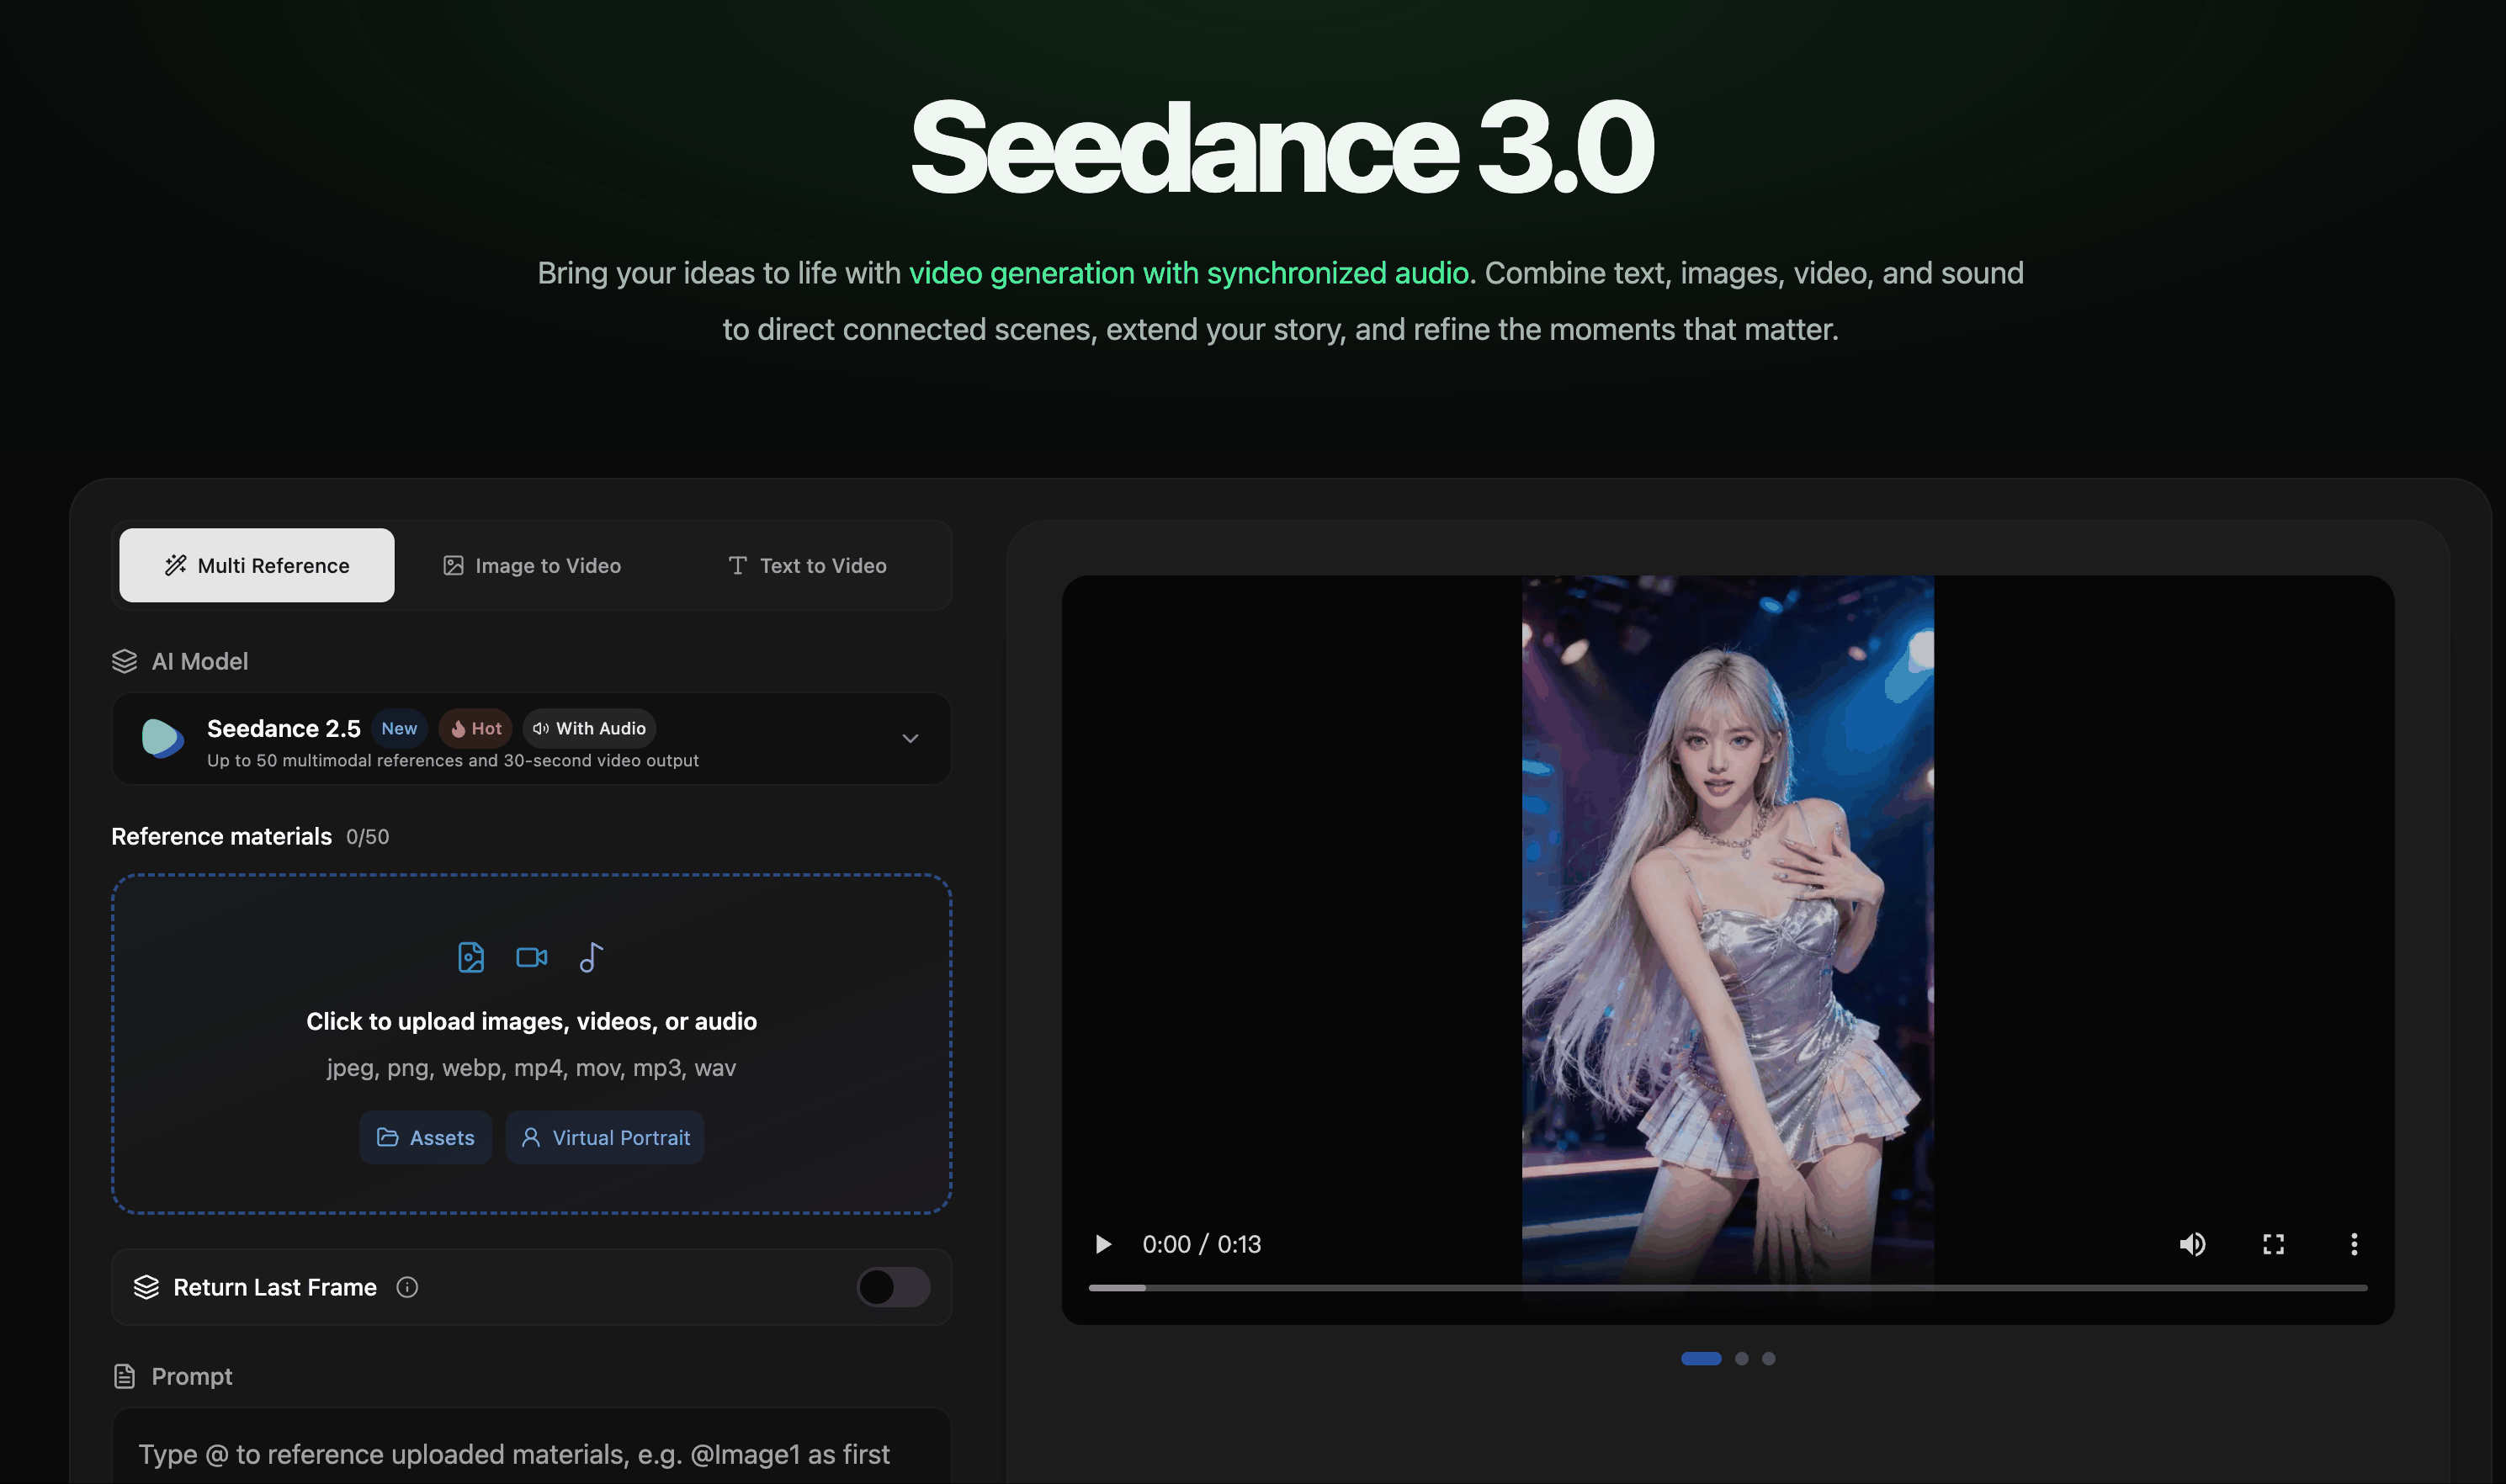
Seedance 3.0 is an AI video generation tool designed to turn text and multimodal references into cinematic videos with synchronized sound. It helps creators guide scenes, maintain visual continuity, and refine both video and audio across a narrative.
What it does
Generates video from text, images, video, and audio references.
- Creates video and audio together in outputs up to 30 seconds.
- Connects shots and scene changes to develop longer narrative sequences.
- Extends existing videos with new action or connected scenes and supports video editing through described visual or audio changes.
Key features
- Combine up to 50 multimodal references to guide characters, settings, visual effects, sound, framing, mood, and rhythm.
- Direct pacing, action, choreography, and camera movement using text and reference videos.
- Carry character appearance, clothing, props, voices, color palettes, lighting, and visual style across connected shots.
- Generate voices, environmental ambience, and sound effects alongside visuals, with audio references for vocal character, mood, and rhythm.
- Select 480p, 720p, or 1080p resolution, use a 5-second duration setting, and generate up to 10 videos in a batch with the same settings.
- Reuse images, videos, and audio from prior creations, upload image files, and add an end frame. What makes it different Seedance 3.0 emphasizes combined visual and audio direction rather than treating sound as a separate step. Its multimodal reference workflow is intended to preserve details across scenes while allowing creators to shape cinematic motion, connected narrative development, and scene-specific sound.